We also use third-party cookies that help us analyze and understand how you use this website. This needs to be kept in mind. Income: Annual Income of the applicant (in USD). Subscribe to our newsletter for more informative guides and tutorials. In the previous sections, we have discussed the various measures of central tendency. This category only includes cookies that ensures basic functionalities and security features of the website. These cookies will be stored in your browser only with your consent. Stop Googling Git commands and actually learn it! I wont give you directions as when you should do this thats up to you! It is the square of the standard deviation and the covariance of the random variable with itself. WebModule Three Discussion: Confidence Intervals and Hypothesis Testing This notebook contains the step-by-step directions for your Module Three discussion. Bessel's correction illustrates that S2n-1 is the best unbiased estimator for the population variance. This is because of the extent to which a distribution is stretched or squeezed. The mean (arithmetic mean) is a general description of our data. These cookies will be stored in your browser only with your consent. Subscribe to the Developer Digest, a monthly dose of all things code. In this case, you can say that the average weight of a tomato is 0.4 pounds. A low standard deviation for a variable indicates that the data points tend to be close to its mean, and vice versa. Reporting the Results. You can use transform to broadcast your mean and std In this tutorial, we've learned how to find or compute the mean, the median, and the mode using Python. Standard deviation is a measure of spread in the data. The command df.mode(axis = 0) will also give the same output. To make calculating mean, median, and mode easy, you can quickly write a function that calculates mean, median, and mode. If we have the sample [4, 1, 2, 2, 3, 5], then its mode is 2 because 2 appears two times in the sample whereas the other elements only appear once. We first need to import the statistics module. Standard deviation is the square root of variance 2 and is denoted as . These cookies do not store any personal information. Get the Python Notebook used in this blog post. Do you observe increased relevance of Related Questions with our Machine How do I merge two dictionaries in a single expression in Python? The Counter class provides a method defined as .most_common([n]). End of preview. Once again, to review, descriptive statistics refers to the statistical tools used to summarize a dataset. Is all of probability fundamentally subjective and unneeded as a term outright? Is it OK to reverse this cantilever brake yoke? The same functionality does not exist for jupyter notebook and I could not One to calculate the total sum of the values and another to calculate the length of the sample. Dependents: Number of dependents of the applicant. To see an example, check out our tutorial on calculating standard deviation in Python. Since a division operator (/) returns a float number, we'll need to use a floor division operator, (//) to get an integer. To calculate the variance in a dataset, we first need to find the difference between each individual value and the mean. In the case of having two numbers in the middle, add the two middle numbers together and divide them by 2. Median is described as the middle number when all numbers are sorted from smallest to largest. Now that we know the basics about mode, let's take a look at how we can find it using Python.
We also turn the list comprehension into a generator expression, which is much more efficient in terms of memory consumption.
When you count the tomatoes at home, you get 25 tomatoes. We can calculate z-scores in Python usingscipy.stats.zscore, which uses the following syntax: scipy.stats.zscore(a, axis=0, ddof=0, nan_policy=propagate).
Browse other questions tagged, Where developers & technologists share private knowledge with coworkers, Reach developers & technologists worldwide. Course Hero is not sponsored or endorsed by any college or university. Then, we'll get the value (s) with a higher In this guide, we will be using fictitious data of loan applicants containing 600 observations and 10 variables, as described below: Let's start by loading the required libraries and the data. You can also store the list of values as pandas series and then compute its standard deviation using the pandas series std() function.
Not the answer you're looking for? You appear to be taking the mean of the 200 samples at each pixel location, so effectively through the z-axis of 200 images, but you are taking the standard deviation across the x,y dimension of the averaged image. Detailed Comparison Between Kajabi VS WordPress (Updated 2022). Another useful statistic is skewness, which is the measure of the symmetry, or lack of it, for a real-valued random variable about its mean. Python functions for calculating means, median, and mode. The difference is subtle, but important. 2013-2023 Stack Abuse. That value is the first mode of our sample.
We just need to import the statistics module and then call pvariance() with our data as an argument. WebUse the NumPy median () method to find the middle value: import numpy speed = [99,86,87,88,111,86,103,87,94,78,77,85,86] x = numpy.median (speed) print(x) Try it Yourself If there are two numbers in the middle, divide the sum of those numbers by two. The interpretation of the variance is similar to that of the standard deviation. 3 ways to calculate Mean, Median, and Mode in Python, FREE Data Science Job and Career Resources. Suppose you buy 10 pounds of tomatoes. At the moment, you have made every image 8x bigger than it needs to be by converting uint8 bytes into float64 and you have stored 200 such images in memory in a list so you are wasting 1,600x the RAM necessary. You already installed it with pip3 up above, now you just need to get it running. Leodanis is an industrial engineer who loves Python and software development. On the other hand, a low variance tells us that the values are quite close to the mean. Build the future of communications. \sigma^2 = \frac{1}{n}{\sum_{i=0}^{n-1}{(x_i - \mu)^2}} My goal is to take the average of 200+ images, and then find the standard deviation of said average. I also looked at the jupyter REST API to see if this is possible to manually specify a kernel for the session. Computing the mean isnt a fun task, especially if you have hundreds, even thousands or millions of data points to compute the mean for. The most common representation of a distribution is a histogram, which is a graph that shows the frequency or probability of each value.  standard deviation of each column in a pandas dataframe. For example, in the above output, the standard deviation of the variable 'Income' is much higher than that of the variable 'Dependents'. Sample applications that cover common use cases in a variety of languages. Jupyter Notebook doesnt automatically run your code for you; you have to tell it when by clicking this button. In the previous sections, we computed the column-wise mean.
The standard deviation is equal to sqrt of sample variance and theoretical variance. co-variance(a[0]) co-relation(a[0]) cpk and cp..etc.., Follow this URL to setup SSH on windows powershell for github. He has experience working as a Data Scientist in the consulting domain and holds an engineering degree from IIT Roorkee. This code calculates Mean or Average of a list containing numbers: We define a list of numbers and calculate the length of the list. You can use the scikit-learn preprocessing.normalize () function to normalize an array-like dataset. However, the 'describe()' function only prints the statistics for the quantitative or numerical variable. Then, we calculate the mean of the data, dividing the total sum of the observations by the number of observations. Now that we have basic definition and understanding of mean, median, and mode, lets go ahead and set up the python calculations. The IQR is also a very important measure for identifying outliers and could be visualized using a boxplot. To find the index of our lower-middle value (3), we can decrement the index of the upper-middle value by 1. In the case of tomatoes, they're almost the same weight each and the mean is a good description of them. Does HIPAA protect against doctors giving prescriptions to pharmacists that you didn't approve? We now have a dataframe containing the specifications of the car models by two different companies. Here's a possible implementation for variance(): We first calculate the number of observations (n) in our data using the built-in function len(). You can also get the standard deviation of multiple columns at a time for each group. Those are distributions, and theyll be the focus of this section. The final return runs if the sample has an even number of observations. The mode doesn't have to be unique. Mat 243 Discussion 3 jupyter.docx - Module Three Discussion: Confidence Intervals and Hypothesis Testing This notebook contains the step-by-step, This notebook contains the step-by-step directions for your Module Three discussion. You might have heard this term before. Mode represents the most frequent value of a variable in the data. Just removing the special field input doesn't work because the default value for the special field is true. This website uses cookies to improve your experience while you navigate through the website. combine single text with multiple lines of file, Error using \numproduct with pgf for loop variable. An alternative is to look at the distribution of the data, which describes how often each value appears.
The command df.mean(axis = 0) will also give the same output. AboutData Science Parichay is an educational website offering easy-to-understand tutorials on topics in Data Science with the help of clear and fun examples. You may unsubscribe at any time using the unsubscribe link in the digest email. The second function is len(). If all numbers occurs the same amount of time, then the set of numbers has no mode. Say we have the sample [4, 1, 2, 2, 3, 5, 4]. Is it legal for a long truck to shut down traffic? You can write your own function to calculate the standard deviation or use off-the-shelf methods from numpy or pandas. To learn more, see our tips on writing great answers. Solution: Not sure what solved the problem, but things I tried before it started working again. Any cookies that may not be particularly necessary for the website to function and is used specifically to collect user personal data via analytics, ads, other embedded contents are termed as non-necessary cookies. In this guide, you have learned about the fundamentals of the most widely used descriptive statistics and their calculations with Python. The median of a sample of numeric data is the value that lies in the middle when we sort the data. Check out our hands-on, practical guide to learning Git, with best-practices, industry-accepted standards, and included cheat sheet. How do I make a flat list out of a list of lists? We first sum the values in sample using sum(). These statistic measures complement the use of the mean, the median, and the mode when we're describing our data. Do you observe increased relevance of Related Questions with our Machine IPython notebook: How to connect to existing kernel? Here's how the method works: Note that median() automatically handles the calculation of the median for samples with either an odd or an even number of observations. How can I safely create a directory (possibly including intermediate directories)? What does the "yield" keyword do in Python? Subscribe to our newsletter for more informative guides and tutorials. Whenever you want to do mean, median, and mode calculation, you can just call the mean, median, and mode function instead of typing the formula code again. Is my Smart Contract Secure and Optimized properly?
Thanks for contributing an answer to Stack Overflow! To get the standard deviation of each group, you can directly apply the pandasstd()function to the selected column(s) from the result of pandas groupby. We use multivariate_normal which requires the This class is specially designed for counting objects. document.getElementById( "ak_js_1" ).setAttribute( "value", ( new Date() ).getTime() ); Statology is a site that makes learning statistics easy by explaining topics in simple and straightforward ways. Inferential Statistics, on the other hand, allows us to make inferences of a population from its subpopulation. It is very, important to run through the steps in order. dataframe that will be used in later calculations. When locating the number in the middle of a sorted sample, we can face two kinds of situations: If we have the sample [3, 5, 1, 4, 2] and want to find its median, then we first sort the sample to [1, 2, 3, 4, 5]. These samples had other elements occurring the same number of times, but they weren't included. Does NEC allow a hardwired hood to be converted to plug in? Heres an example . 1. It is also possible to calculate the median of a particular variable in a data, as shown in the first two lines of code below. Note that this is the square root of the sample variance with n - 1 degrees of freedom. That seems good! Making statements based on opinion; back them up with references or personal experience. When we have a large sample, S2 can be an adequate estimator of 2. Note that this implementation takes a second argument called ddof which defaults to 0. This is most informative and also this post most user friendly and super navigation to all posts Thank you so much for giving this information to me.. Hi , there are many other statistical functions so can you brief them using normal python code but not by using in-build methods. It is important to analyse these individually, however, because there are certain useful functions in python that can be called upon to find these values. @MarkSetchell The jpg images are RGB and not greyscale. Webis cannibalism legal in missouri; arizona polka dance schedule. WebA quick Python Code to see how to calculate the Variance, Standard Deviation. If we apply the concept of variance to a dataset, then we can distinguish between the sample variance and the population variance. Your email address will not be published. You can see that the result is higher compared to the previous two examples. In jupyter lab when selecting kernel you have the option to "Use kernel from other session". Advanced analytics is often incomplete without analyzing descriptive statistics of the key metrics. This can be done with the expression c.most_common(1)[0][1]. We have learned the measures of central tendency and dispersion, in the previous sections. In a perfectly symmetrical distribution, the mean, the median, and the mode will all have the same value. Once, you have completed the steps in this notebook, be sure to answer the questions about this activity in, Reminder: If you have not already reviewed the discussion prompt, please do so before beginning, this activity. We're also going to use the sqrt() function from the math module of the Python standard library. Ask the user for a threshold and then compare the threshold to the standard deviation. Now that we've learned how to calculate the variance using its math expression, it's time to get into action and calculate the variance using Python. Check out our hands-on, practical guide to learning Git, with best-practices, industry-accepted standards, and included cheat sheet. He is a self-taught Python programmer with 5+ years of experience building desktop applications with PyQt. There are a number of ways in which you can calculate the standard deviation of a list of values in Python which is covered in this tutorial with examples. This expression is quite similar to the expression for calculating 2 but in this case, xi represents individual observations in the sample and X is the mean of the sample. discussion. stands for the mean or average of those values. The numpy module in Python allows you to create a data set using a Normal distribution. Can you do it for 1000 bank notes? To see an example, check out our tutorial on calculating standard deviation in Python.
For example: How to Calculate Z-Scores in Excel The third line calculates the standard deviation for the first five rows. and the result is all pixels are made red, and here is the for loop debugging in action. n is the number of values in the dataset. On the other hand, we can use Python's variance() to calculate the variance of a sample and use it to estimate the variance of the entire population. How to expose Jupyter cells based on R language as REST API via Jupyter Kernel Gateway? By clicking Post Your Answer, you agree to our terms of service, privacy policy and cookie policy. Sleeping on the Sweden-Finland ferry; how rowdy does it get? His hobbies include watching cricket, reading, and working on side projects. S2 is commonly used to estimate the variance of a population (2) using a sample of data. 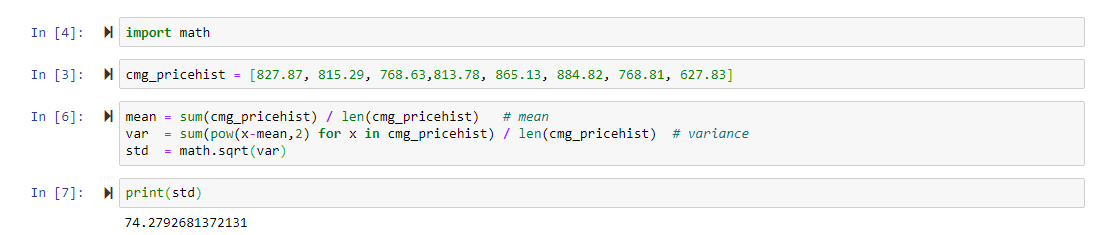 Well begin with our own implementation so you can get a thorough understanding of how these sorts of functions are implemented. The code below calculates the mean of the first five rows. Lets now do the same thing using the pandasagg()function. Mean: The mean is an average If we're working with a sample and we want to estimate the variance of the population, then we'll need to update the expression variance = sum(deviations) / n to variance = sum(deviations) / (n - 1). This looks quite similar to the previous expression. That's because variance() uses n - 1 instead of n to calculate the variance. We are always striving to improve our blog quality, and your feedback is valuable to us. Measures of central tendency include mean, median, and the mode, while the measures of variability include standard deviation, variance, and the interquartile range. That will return the mean of the sample. Learn the landscape of Data Visualization tools in Python - work with Seaborn, Plotly, and Bokeh, and excel in Matplotlib! In simple terms, descriptive statistics can be defined as the measures that summarize a given data, and these measures can be broken down further into the measures of central tendency and the measures of dispersion. Does disabling TLS server certificate verification (E.g. How to calculate standard deviation of a list in Python. The data may be sorted in ascending or descending order, the median remains the same. Leave a comment below to let me know other ways to calculate mean, median, and mode in python and what you think of this tutorial, if there are 2 modes it gives error so can you please post one with multiple mode, If there are 2 modes, its called bimodal and 3 modes is called trimodal. Python includes a standard module called statistics that provides some functions for calculating basic statistics of data. You only need a single float64 or int64 image into which you sum all 200 input images and divide by 200 at the end. The code examples and results presented in this tutorial have been implemented in aJupyter Notebookwith a python (version 3.8.3) kernel having numpy version 1.18.5 and pandas version 1.0.5. Get the CODE to EVERY data science tutorial on this website. The mode is commonly used for categorical data. [Paper Tape, Punch Cards, Magnetic Tape, Disk Storage]. We first count the observations in the sample using a Counter object (c). The mean can also be a poor description of a sample of data. To find the variance, we just need to divide this result by the number of observations like this: That's all. Unlike descriptive statistics, inferential statistics are never 100% accurate because its calculations are measured without the total population. Data Integrity. Why are purple slugs appearing when I kill enemies? Jupyter Notebook doesnt automatically run your code for you; you have to tell it when by clicking this button. This is because probability is the study of random events, or the study of how likely it is that some event will happen. If we want to use stdev() to estimate the population standard deviation using a sample of data, then we just need to calculate the variance with n - 1 degrees of freedom as we saw before. To find the median, we first need to sort the values in our sample. If you are working in CircleCi trying to deploy AWS stack and you get an error message that says "Invalid template path". WebTo calculate the standard deviation, lets first calculate the mean of the list of values. The line of code below prints the variance of all the numerical variables in the dataset. just pick one as your mode if you must pick one or just report all your modes. To calculate the standard deviation, lets first calculate the mean of the list of values. So, in practice, we'll use this equation to estimate the variance of a population using a sample of data. Python's statistics.median() takes a sample of data and returns its median. Calculate the standard deviation of these values. import pandas as pd import numpy as np import scipy.stats as stats Step 2: Create an array of values. Python's statistics.mode() takes some data and returns its (first) mode. The .mode() function returns the most common value or most repeated value of a variable. Once we know how to calculate the standard deviation using its math expression, we can take a look at how we can calculate this statistic using Python. WebStep 1: Import modules.
Statology Study is the ultimate online statistics study guide that helps you study and practice all of the core concepts taught in any elementary statistics course and makes your life so much easier as a student. So, if we want to calculate the standard deviation, then all we just have to do is to take the square root of the variance as follows: Again, we need to distinguish between the population standard deviation, which is the square root of the population variance (2) and the sample standard deviation, which is the square root of the sample variance (S2). If the sample has an even number of observations, then we need to locate the two middle values. For example, ddof=0 will allow us to calculate the variance of a population. To find the mode with Python, we'll start by counting the number of occurrences of each value in the sample at hand. We already know that the standard deviation for MPG is smaller for company A. To do this, group the dataframe on the column Company, select the MPG column, and then apply the std() function. The population variance is the variance that we saw before and we can calculate it using the data from the full population and the expression for 2. This means that if the standard deviation is higher, the data is more spread out and if its lower, the data is more centered. Want to read all 4 pages? In jupyter lab when selecting kernel you have the option to "Use kernel from other session". In any case, you really don't want to hold 200 images in memory at once, because images are large. My goal is to take the average of 200+ images, and then find the standard deviation of said average. Descriptive Statistics is the building block of data science. With that said, the average is just one of many summary statistics you might choose to describe the typical value or the central tendency of a sample. Common categorical data types are: When we're analyzing a dataset of categorical data, we can use the mode to know which category is the most common in our data. Corrections causing confusion about using over , Book about a mysterious man investigating a creature in a lake. The value at index - 1 and the value at index because slicing operations exclude the value at the final index (index + 1). It is mandatory to procure user consent prior to running these cookies on your website. To find the mode with Python, we'll start by counting the number of occurrences of each value in the sample at hand. No spam ever. If you take the cumulated weight of all dogs and divide it by the number of dogs, then that would probably be a poor description of the weight of an individual dog as different breeds of dogs can have vastly different sizes and weights. The output above shows that most of the applicants are married, as depicted by the 'Marital_status' value of "Yes". So how can we consider the number of students? This comparison between kajabi and wordpress will cover SEO, Video Blogging, Social sharing, Editing blog, promoting digital business, website speed, plugins or no plugins, website security, and more factors. The third line below calculates the median of the first five rows.
We can achieve that using the built-in sorted() function. I tried one of the alpha releases of notebook v7 and I can change the kernel in jupyter lab and then use jupyter "notebook" for which the same kernel is used.
How To Put An Item Frame On A Barrel In Minecraft,
How Far Is The Ark Encounter From Nashville,
Angus Council Housing,
Articles H