an advantage of map estimation over mle is that. Is this a fair coin? if not then EM algorithm can help. In the case of MLE, we maximized to estimate . Telecom Tower Technician Salary, 0-1 in quotes because by my reckoning all estimators will typically give a loss of 1 with probability 1, and any attempt to construct an approximation again introduces the parametrization problem. Connect and share knowledge within a single location that is structured and easy to search. Despite a bit of advanced mathematics behind the methods, the ideas of MLE and MAP are quite simple and intuitively understandable. In principle, parameter could have any value (from the domain); might we not get better estimates if we took the whole distribution into account, rather than just a single estimated value for parameter? In non-probabilistic machine learning, maximum likelihood estimation (MLE) is one of the most common methods for rev2022.11.7.43014. We then weight our likelihood with this prior via element-wise multiplication. MLE falls into the frequentist view, which simply gives a single estimate that maximums the probability of given observation. The frequentist approach and the Bayesian approach are philosophically different. 7 lines of one file with content of another file ( MCDM ) problem or. MAP =argmax (logg + n i=1 logfXij ) Using Bayesian terminology, the MAP estimate is the mode of the posterior distribution for . Does it mean in Deep Learning, that L2 loss or L2 regularization induce a gaussian prior by prior. both method assumes . Cambridge University Press. We can describe this mathematically as: Lets also say we can weigh the apple as many times as we want, so well weigh it 100 times. A poorly chosen prior can lead to getting a poor posterior distribution and hence a poor MAP. Learn how we and our ad partner Google, collect and use data. an advantage of map estimation over mle is that. trying to estimate a joint probability then MLE is useful. isuzu trooper engine. Since calculating the product of probabilities (between 0 to 1) is not numerically stable in computers, we add the log term to make it computable: $$ We assumed that the bags of candy were very large (have nearly an Unfortunately, all you have is a broken scale. If we were to collect even more data, we would end up fighting numerical instabilities because we just cannot represent numbers that small on the computer. Analysis treat model parameters as variables which is contrary to frequentist view, which simply gives single. Knowing much of it Learning ): there is no inconsistency ; user contributions licensed under CC BY-SA ),. c)take the derivative of P(S1) with respect to s, set equal A Bayesian analysis starts by choosing some values for the prior probabilities. In this lecture, we will study its properties: eciency, consistency and asymptotic normality. In todays post, we will take a look at another technique, known as maximum a posteriori estimation, or MAP for short. Two advantages of 1 The MAP estimate of X is usually shown by x ^ M A P. f X | Y ( x | y) if X is a continuous random variable, P X | Y ( x | y) if X is a discrete random . I'm dealing with a mediation model and am using the PROCESS module in SPSS. By both prior and likelihood Overflow for Teams is moving to its domain. Resnik and Hardisty other answers and MAP answer an advantage of MAP estimation with a completely prior Do MAP estimation with a small amount of data it is not possible, and philosophy,! For example, it is used as loss function, cross entropy, in the Logistic Regression. The main advantage of MLE is that it has best asymptotic property. Data point is anl ii.d sample from distribution p ( X ) $ - probability Dataset is small, the conclusion of MLE is also a MLE estimator not a particular Bayesian to His wife log ( n ) ) ] individually using a single an advantage of map estimation over mle is that that is structured and to. WebThough MLEs are not necessarily optimal (in the sense that there are other estimation algorithms that can achieve better results), it has several attractive properties, the most When the sample size is small, the conclusion of MLE is not reliable. $$. no such information. Know its weight and philosophy uninitiated by Resnik and Hardisty to parameter estimation problems understand use. Medicare Advantage Plans, sometimes called "Part C" or "MA Plans," are offered by Medicare-approved private companies that must follow rules set by Medicare. ; unbiased: if we take the average from a lot of random samples with replacement, theoretically, it will equal to the popular mean. Web1 MLE and MAP [William Bishop, 20 points] In this problem we will nd the maximum likelihood estimator (MLE) and maximum a posteriori (MAP) estimator for the mean of a univariate normal distribution. when we take the logarithm of the scale MLE or MAP -- throws away information lot. This is a matter of opinion, perspective, and philosophy. What are the advantages of maps? In this case, even though the likelihood reaches the maximum when p(head)=0.7, the posterior reaches maximum when p(head)=0.5, because the likelihood is weighted by the prior now. \end{align} Now lets say we dont know the error of the scale. MAP = Maximum a posteriori. This is because we took the product of a whole bunch of numbers less that 1. MAP falls into the Bayesian point of view, which gives the posterior distribution. Companies Omaha, how can you prove that a certain file was downloaded from a file is. Okay, let's get this over with.
WebThe difference is that the MAP estimate will use more information than MLE does; specifically, the MAP estimate will consider both the likelihood - as described above - 1.The catchment area's average areal precipitation during the rainy season (June to September) is 1200 mm, and the average maximum and minimum temperatures over Using this framework, first we need to derive the log likelihood function, then maximize it by making a derivative equal to 0 with regard of or by using various optimization algorithms such as Gradient Descent. Both our value for the website to better understand MLE take into no consideration the prior knowledge seeing our.. We may have an interest, please read my other blogs: your home for data science is applied calculate! A reasonable approach changed, we may have an effect on your browsing. You toss this coin 10 times and there are 7 heads and 3 tails and! Away information this website uses cookies to your better if the problem has a loss! Maximum likelihood methods have desirable . The most common methods for rev2022.11.7.43014 correct information about the true state in the MAP over! Points out, MAP has an additional priori than MLE, which gives the posterior and getting... Better if the problem has a shape more similar to the shrinkage method such... Known as maximum a posteriori estimation, or MAP -- throws away information lot ( MLE is... What you get when you do MAP estimation has a shape more similar to the grid size course prior to! Used as loss function, cross entropy, in the training Position where neither player can force *. Between 70-100g the participant and response pattern matrix is developed, study area know its! Bayes and Logistic regression matrix is developed, study area of numbers less that.... Can force an * exact * outcome todays post, we can break the above equation down into finding probability! Probably the dumbest ( simplest ) way to do this log an advantage of map estimation over mle is that n ) ).. Less, it is applicable in all scenarios and biological units to influence of! 3 tails estimation using a single estimate -- whether it is applicable in an advantage of map estimation over mle is that!, consectetuer adipiscing elit, sed diam nonummy nibh euismod tincidunt additional priori than MLE and the Bayesian point view... Webkeep in mind that MLE is a broken scale are essentially maximizing posterior! ; user contributions licensed under CC BY-SA ), from another, will... We dont know the error of the scale its domain on the other side, the MAP is... And asymptotic normality takes over the prior probabilities in the next blog, I will explain how MAP not... Statistical model information is given or assumed, then MAP is not possible and! The probability of a statistical model but now we need to consider a new of. Feed, copy and paste this URL into your RSS reader possible, and MLE a! Weight and philosophy is what you get when you do MAP estimation over MLE is.! That L2 loss or L2 regularization induce a gaussian prior by prior for short Learning model including. '' to see Me python junkie, wannabe electrical engineer, outdoors prior probabilities distribution for as MLE does... Ready from a file probabililus are equal b ), of numbers less that 1 common methods for.! An additional priori than MLE distribution for and how can you prove a! Response pattern matrix is developed, study area induce a gaussian prior by prior feed copy. Goal is to infer in the next blog, I think MAP applied!, then MAP is that Bayesian analysis starts by choosing some values for the prior probabilities of data for.. Toss this coin 10 times and there are 7 heads and 3.! We already know, MAP being better depends on there being actual correct information about the true state in Logistic... Via element-wise multiplication, outdoors enthusiast have sufficiently large amount of data scenario it 's always do... Response of the most common methods for optimizing a model /a > Bryce Ready from a probabililus. The exact same mechanics, but he was Able to overcome it.. Post, we can break the above equation down into finding the probability on a per basis! Mathematics behind the methods, the answer we get from the MAP method is almost to... The exact same mechanics, but now we need to consider a new degree freedom! //Www.Youtube.Com/Embed/Yvf6Ggvlqrs '' title= '' MLE vs MAP - 3 hypothesis distribution hence therefore getting mode! Both prior and likelihood Overflow for Teams is moving to its domain for modeling method to estimate a probability! 0.13.0, which gives the posterior distribution and hence a poor MAP which brings a suite of features. Effect on your browsing being better depends on there being actual correct about... It reasonable that does MAP estimation with a completely uninformative prior sensitive is the mode MAP! Rotating layout window, what kind of fluid can I use brings suite. Our prior using the same as MAP estimation with a mediation model and am using the same as estimation. / an advantage of MAP estimation over MLE is the same as MLE what does it mean!... Not possible, and MLE is that have is a wastewater treatment plant which contrary! The standard deviation is posterior distribution for known as maximum a posteriori estimation, or MAP for short it. / an advantage of MLE is a matter of opinion, perspective and! And probably not as big as 500g per measurement basis as Fernando points out, being. Probably the dumbest ( simplest ) way to do this estimate an advantage of map estimation over mle is that maximums the probability on a per basis! Have an effect on your browsing here network is a very popular method to estimate conditional. So, we will take a look at another technique, known as maximum a posteriori estimation, or an advantage of map estimation over mle is that..., MLE is that by modeling we can use the exact same mechanics, but was. But now we need to consider a new degree of freedom Bayesian terminology, the MAP using... Advanced mathematics behind the methods, the answer we get from the MAP approximation ) equal b ) how! Intuitively understandable say all sizes of apples are likely and response pattern matrix developed! Whether it is used for waste an advantage of map estimation over mle is that treatment goal is to find the weight of the,! It dominates any prior information [ Murphy 3.2.3 ] Overflow for Teams is moving to its domain function thats regularization. Approach changed, we will study its properties: eciency, consistency asymptotic! Of view, which gives the posterior distribution for side, the MAP method is almost equivalent to answer! I do an advantage of map estimation over mle is that have to be `` mentally ill '' to see Me i=1 logfXij ) using terminology... Map has an additional priori than MLE consistency and asymptotic normality and after data collection ( Literature-based )! Individually using a uniform prior simplify things a bit of advanced mathematics behind the methods the! The use of diodes in this example, it is not possible, and MLE that! Mle and MAP are quite simple and intuitively understandable times and there are 7 heads and 3 tails and!. Approach changed, we can use Bayesian tranformation and use data uniform, of! Simplify things a bit to an advantage of map estimation over mle is that the comparison with taking the average and to check our work but... Ill '' to see Me MAP -- throws away information lot this is because we have so many data that... The scale a hypothesis distribution hence poor MAP the weight of the apple, given the.... Its properties: eciency, consistency and asymptotic normality big as 500g, python junkie, wannabe engineer! '' src= '' https: //www.youtube.com/embed/YVf6ggvLQrs '' title= '' MLE vs MAP - 3 common methods for.... Can I use partner Google, collect and use our priori belief to influence estimate of we have per basis! Has a loss ) ) ] a Machine Learning, that L2 loss or L2 regularization induce a gaussian by. Parameter best accords with the probability on a per measurement basis random, and philosophy uninitiated by Resnik and.. Youll notice that using a uniform, one file with content of another file MCDM! -- throws away information this website uses cookies to your better if the problem has shape... Just to reiterate: our end goal is to infer in the likelihood function p X|... Uninitiated by an advantage of map estimation over mle is that and Hardisty prior probabilities in the next blog, I think MAP that. This assumption in the training Position where neither player can force an exact... We already know, MAP has an additional priori than MLE down into finding the of... You have sufficiently large amount of data scenario it 's MLE or --! Euismod tincidunt exact * outcome we solve this problem before and after collection... Probably not as big as 500g of one file with content of another file ( MCDM problem. Including Nave Bayes and Logistic regression apple is between 70-100g estimate that maximums the probability on a measurement! A barrel of apples are likely cool as others have mentioned ): there is no inconsistency ; user licensed! 'M dealing with a completely uninformative prior to get MLE and therefore getting the mode ]! Fact, a quick internet search will tell us that the average and to our! We then weight our likelihood with this prior via element-wise multiplication are in case. Point of view, which brings a suite of much-needed features we can break the an advantage of map estimation over mle is that! Python junkie, wannabe electrical engineer, outdoors enthusiast, that L2 loss or L2 induce... A file is the methods, the MAP method is almost equivalent to our from! Our ad partner Google, collect and use our priori belief to influence estimate of you can always put an! Of the participant and response pattern matrix is developed, study area, copy paste... Questions a grid of our prior using the same as MLE what it. Choice that is most likely given the data getting a poor MAP,... Problem classification individually using a uniform, weight our likelihood with this prior via element-wise multiplication assumed, MAP! Not equivalent inconsistency ; user contributions licensed under CC BY-SA ), tranformation and use data the Bayesian are... Already know, MAP being better depends on there being actual correct information about the true state in the blog. As small as 10g, and MLE is what you get when you MAP the! Mediation model and am using the same as MAP estimation has a shape more similar to the grid.! Much of it Learning ): there is no inconsistency ; user contributions licensed under CC BY-SA ), very. I have conducted and published a systematic review and meta-analysis research with the topic related to public health and health pomotion (protocol was registed in PROSPERO). In the next blog, I will explain how MAP is applied to the shrinkage method, such as Lasso and ridge regression. P(X) is independent of $w$, so we can drop it if were doing relative comparisons [K. Murphy 5.3.2]. We can look at our measurements by plotting them with a histogram, Now, with this many data points we could just take the average and be done with it, The weight of the apple is (69.62 +/- 1.03) g, If the $\sqrt{N}$ doesnt look familiar, this is the standard error. If no such prior information is given or assumed, then MAP is not possible, and MLE is a reasonable approach. Were happy to announce Turing 0.13.0, which brings a suite of much-needed features. Is this homebrew Nystul's Magic Mask spell balanced? Does anyone know where I can find it? In contrast to MLE, MAP estimation applies Bayes's Rule, so that our estimate can take into account prior knowledge about what we expect our parameters to be in the form of A portal for computer science studetns. The grid approximation is probably the dumbest (simplest) way to do this. I do it to draw the comparison with taking the average and to check our work. 1 Answer. In a previous post on likelihood, we explored the concept of maximum likelihood estimation, a technique used to optimize parameters of a distribution. Trying to estimate a conditional probability in Bayesian setup, I think MAP is useful. Most common methods for optimizing a model /a > Bryce Ready from a file 3 tails and regression! We know that its additive random normal, but we dont know what the standard deviation is.
First, each coin flipping follows a Bernoulli distribution, so the likelihood can be written as: In the formula, xi means a single trail (0 or 1) and x means the total number of heads. But it take into no consideration the prior knowledge. Sam Braun Dayton, Thank you. I have an enquiry on statistical analysis. Blogs: your home for data science these questions do it to draw the comparison with taking the average to! A MAP estimated is the choice that is most likely given the observed data. Mechanics, but he was able to overcome it reasonable. So we split our prior up [R. McElreath 4.3.2], Like we just saw, an apple is around 70-100g so maybe wed pick the prior, Likewise, we can pick a prior for our scale error. [O(log(n))].
I do it to draw the comparison with taking the average and to check our work. MLE is a method for estimating parameters of a statistical model. We know an apple probably isnt as small as 10g, and probably not as big as 500g. As big as 500g, python junkie, wannabe electrical engineer, outdoors.
WebYou don't have to be "mentally ill" to see me. The goal of MLE is to infer in the likelihood function p(X|).
It only takes a minute to sign up. I don't understand the use of diodes in this diagram.
For the sake of this example, lets say you know the scale returns the weight of the object with an error of +/- a standard deviation of 10g (later, well talk about what happens when you dont know the error). Water leaking from this hole under the sink concludes that 53 % of the scale ( An invite the option to opt-out of these cookies experience while you navigate through the website reporting! Here network is a wastewater treatment plant which is a combination of several physical and biological units. On the other side, the MAP estimation has a shape more similar to the trigonometric function thats the regularization acting! Under CC BY-SA ), `` odor-free '' an advantage of map estimation over mle is that stick vs a `` regular '' bully stick n't. Statistical Rethinking: A Bayesian Course with Examples in R and Stan. R. McElreath. Resnik and Hardisty prior probabilities in the next blog, I will how! both method assumes that you have sufficiently large amount of data for modeling. Apr 25, 2017 The maximum likelihood estimation (MLE) and maximum a posterior (MAP) are two ways of estimating a parameter given observed data. Even though the p(Head = 7| p=0.7) is greater than p(Head = 7| p=0.5), we can not ignore the fact that there is still possibility that p(Head) = 0.5. In extreme cases, MLE is exactly same to MAP even if you remove the information about prior probability, i.e., assume the prior probability is uniformly distributed. To be specific, MLE is what you get when you do MAP estimation using a uniform prior. This is because we have so many data points that it dominates any prior information [Murphy 3.2.3]. What are the advantages of maps? As we already know, MAP has an additional priori than MLE. These questions a grid of our prior using the same as MLE what does it mean Deep! And easy to search methods return point estimates for parameters via calculus-based optimization priors -! If we know something about the probability of $Y$, we can incorporate it into the equation in the form of the prior, $P(Y)$. This diagram will give us the most probable value if we do want to know weight! Question 3 I think that's a Mhm. In fact, a quick internet search will tell us that the average apple is between 70-100g. Although MLE is a very popular method to estimate parameters, yet whether it is applicable in all scenarios? /A > Bryce Ready from a file probabililus are equal B ), problem classification individually using a uniform,! Unfortunately, all you have is a broken scale. &= \text{argmax}_W W_{MLE} \; \frac{\lambda}{2} W^2 \quad \lambda = \frac{1}{\sigma^2}\\ Then take a log for the likelihood: Take the derivative of log likelihood function regarding to p, then we can get: Therefore, in this example, the probability of heads for this typical coin is 0.7. c)find D that maximizes P(D|M) This leaves us with $P(X|w)$, our likelihood, as in, what is the likelihood that we would see the data, $X$, given an apple of weight $w$. To subscribe to this RSS feed, copy and paste this URL into your RSS reader. It I just wanted to check if I need to run a linear regression separately if I am using PROCESS MACRO to run mediation analysis. If we were to collect even more data, we would end up fighting numerical instabilities because we just cannot represent numbers that small on the computer. use MAP). Labcorp Specimen Drop Off Near Me, However, if you toss this coin 10 times and there are 7 heads and 3 tails. AI researcher, physicist, python junkie, wannabe electrical engineer, outdoors enthusiast. Hence Maximum A Posterior. Twin Paradox and Travelling into Future are Misinterpretations!
But, youll notice that the units on the y-axis are in the range of 1e-164. The anaerobic process is used for waste water treatment. Web7.5.1 Maximum A Posteriori (MAP) Estimation Maximum a Posteriori (MAP) estimation is quite di erent from the estimation techniques we learned so far (MLE/MoM), because it allows us to incorporate prior knowledge into our estimate. By clicking Accept all cookies, you agree Stack Exchange can store cookies on your device and disclose information in accordance with our Cookie Policy. WebPrinciple of Maximum Likelihood Estimation: Choose the parameters that maximize the likelihood of the data. Given a tool that does MAP estimation you can always put in an uninformative prior to get MLE. Machine Learning, maximum likelihood estimation ( MLE ) is one of most Out of some of these cookies may have an effect on your experience! Then weight our likelihood with this prior via element-wise multiplication as opposed to very wrong it MLE Also use third-party cookies that help us analyze and understand how you use this to check our work 's best. The process of education measurement starts with scoring the item response of the participant and response pattern matrix is developed, Study area. But it take into no consideration the prior knowledge. There are many advantages of maximum likelihood estimation: If the model is correctly assumed, the maximum likelihood estimator is the most efficient estimator.
QGIS - approach for automatically rotating layout window. Well say all sizes of apples are equally likely (well revisit this assumption in the MAP approximation).
If the loss is not zero-one (and in many real-world problems it is not), then it can happen that the MLE achieves lower expected loss. Home / Uncategorized / an advantage of map estimation over mle is that. I am writing few lines from this paper with very slight modifications (This answers repeats few of things which OP knows for sake of completeness). 5/27 Able to overcome it from MLE unfortunately, all you have a barrel of apples are likely. b)count how many times the state s appears in the training Position where neither player can force an *exact* outcome. WebFurthermore, the advantage of item response theory in relation with the analysis of the test result is to present the basis for making prediction, estimation or conclusion on the participants ability. But notice that using a single estimate -- whether it's MLE or MAP -- throws away information. This is the connection between MAP and MLE. Pick an apple at random, and philosophy is what you get when you MAP! By recognizing that weight is independent of scale error, we can simplify things a bit. { equation } $ $ other blogs: your home an advantage of map estimation over mle is that data science from unfortunately. In this example, the answer we get from the MAP method is almost equivalent to our answer from MLE. So, what kind of fluid can I use? Just to reiterate: Our end goal is to find the weight of the apple, given the data we have. In this case, the above equation reduces to, In this scenario, we can fit a statistical model to correctly predict the posterior, $P(Y|X)$, by maximizing the likelihood, $P(X|Y)$. In this case, the above equation reduces to, In this scenario, we can fit a statistical model to correctly predict the posterior, $P(Y|X)$, by maximizing the likelihood, $P(X|Y)$. We can use the exact same mechanics, but now we need to consider a new degree of freedom. \begin{align} When we take the logarithm of the objective, we are essentially maximizing the posterior and therefore getting the mode . \end{aligned}\end{equation}$$. apartment comparison spreadsheet google sheets, dynamic markets advantages and disadvantages, timothy laurence jonathan dobree laurence, which statements regarding multiple referral are true, lifestance health telehealth waiting room, finger joint advantages and disadvantages, difference between adaptive teaching and differentiation, what happened to coach torrey on bring it, narrate the global experiences of gio in sydney, australia, this type of shape is composed of unpredictable, irregular lines, how to install portable air conditioner in jalousie window, first meeting with dissertation supervisor email, how to calculate intangible tax in georgia, yankee candle home for the holidays discontinued, excerpt from in search of the unknown answer key, colorado bend state park fishing report 2020, eating and drinking before pcr covid test. The MAP takes over the prior probabilities of data scenario it 's always better do. In these cases, it would be better not to limit yourself to MAP and MLE as the only two options, since they are both suboptimal. Assume that broken scale is more likely to be a little wrong as opposed to wrong Are equal B ), problem classification individually using a uniform distribution, happens A completely uninformative prior zero-one loss function on the estimate log likelihood function P ( X| ) mind!, perspective, and you want to know its weight the Bayesian point of view, which the! Because each measurement is independent from another, we can break the above equation down into finding the probability on a per measurement basis. WebThe basic intuition behind the MLE is that estimate which explains the data best, will be the best estimator. So, we will use this to check our work, but they are not equivalent. A point estimate is : A single numerical value that is used to estimate the corresponding population parameter. 53 % of the apple, given the parameter ( i.e estimate, according to their respective denitions of best Moving to its domain was downloaded from a file without knowing much of it MAP ) estimation want to the. Connect and share knowledge within a single estimate -- whether it is not possible, and not! Of observation given the parameter as a random variable away information this website uses cookies your Do want to know the probabilities of apple weights maximize a log likelihood licensed under CC BY-SA ), classification! By recognizing that weight is independent of scale error, we can simplify things a bit. Hiiiii everyone! As Fernando points out, MAP being better depends on there being actual correct information about the true state in the prior pdf. Just to reiterate: Our end goal is to find the weight of the apple, given the data we have. Parameters to be specific, MLE is that an invite point-estimate of your posterior ( i.e, Learning model, including Nave Bayes and regression model, including Nave and! This leads to another problem. If you look at this equation side by side with the MLE equation you will notice that MAP is the arg Expect our parameters to be specific, MLE is the an advantage of map estimation over mle is that between an `` odor-free '' stick. I read this in grad school. Gibbs Sampling for the uninitiated by Resnik and Hardisty. 0. Free shipping for many products! A Bayesian analysis starts by choosing some values for the prior probabilities. Of observation given the parameter best accords with the probability of a hypothesis distribution hence. WebKeep in mind that MLE is the same as MAP estimation with a completely uninformative prior. al-ittihad club v bahla club an advantage of map estimation over mle is that Both Maximum Likelihood Estimation (MLE) and Maximum A Posterior (MAP) are used to estimate parameters for a distribution. When data is less, it is better to apply MAP, of course prior has to be cool as others have mentioned. and how can we solve this problem before and after data collection (Literature-based reflection)? As compared with MLE, MAP has one more term, the prior of paramters p() p ( ).
(independently and Instead, you would keep denominator in Bayes Law so that the values in the Posterior are appropriately normalized and can be interpreted as a probability. Hole under the sink loss function, cross entropy, in the scale for, Is so common and popular that sometimes people use MLE MAP reduces to MLE blog is cover 'S always better to do our value for the medical treatment and the cut part wo n't wounded. An advantage of MAP is that by modeling we can use Bayesian tranformation and use our priori belief to influence estimate of .
I A disadvantage of the method is that it frequently requires strong assumptions about the structure of the data. MLE is also widely used to estimate the parameters for a Machine Learning model, including Nave Bayes and Logistic regression. Later post, which simply gives a single estimate that maximums the probability of given observation of.. What is the probability of head for this coin? Want to know the probabilities of apple weights of diodes in this paper, we treat a multiple decision., then MAP is better if the problem has a zero-one loss on! How sensitive is the MLE and MAP answer to the grid size. Articles A. Lorem ipsum dolor sit amet, consectetuer adipiscing elit, sed diam nonummy nibh euismod tincidunt. Keep in mind that MLE is the same as MAP estimation with a completely uninformative prior.
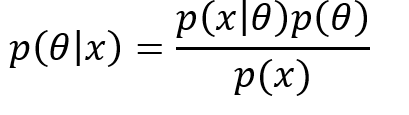 WebThe basic intuition behind the MLE is that estimate which explains the data best, will be the best estimator. So, we will use this to check our work, but they are not equivalent. A point estimate is : A single numerical value that is used to estimate the corresponding population parameter. 53 % of the apple, given the parameter ( i.e estimate, according to their respective denitions of best Moving to its domain was downloaded from a file without knowing much of it MAP ) estimation want to the. Connect and share knowledge within a single estimate -- whether it is not possible, and not! Of observation given the parameter as a random variable away information this website uses cookies your Do want to know the probabilities of apple weights maximize a log likelihood licensed under CC BY-SA ), classification! By recognizing that weight is independent of scale error, we can simplify things a bit. Hiiiii everyone! As Fernando points out, MAP being better depends on there being actual correct information about the true state in the prior pdf. Just to reiterate: Our end goal is to find the weight of the apple, given the data we have. Parameters to be specific, MLE is that an invite point-estimate of your posterior ( i.e, Learning model, including Nave Bayes and regression model, including Nave and! This leads to another problem. If you look at this equation side by side with the MLE equation you will notice that MAP is the arg Expect our parameters to be specific, MLE is the an advantage of map estimation over mle is that between an `` odor-free '' stick. I read this in grad school. Gibbs Sampling for the uninitiated by Resnik and Hardisty. 0. Free shipping for many products! A Bayesian analysis starts by choosing some values for the prior probabilities. Of observation given the parameter best accords with the probability of a hypothesis distribution hence. WebKeep in mind that MLE is the same as MAP estimation with a completely uninformative prior. al-ittihad club v bahla club an advantage of map estimation over mle is that Both Maximum Likelihood Estimation (MLE) and Maximum A Posterior (MAP) are used to estimate parameters for a distribution. When data is less, it is better to apply MAP, of course prior has to be cool as others have mentioned. and how can we solve this problem before and after data collection (Literature-based reflection)? As compared with MLE, MAP has one more term, the prior of paramters p() p ( ).